Onboarding New Hires With AI Agents Trained on Internal Playbooks
AI agents need internal playbooks to move beyond answering questions to completing onboarding tasks.
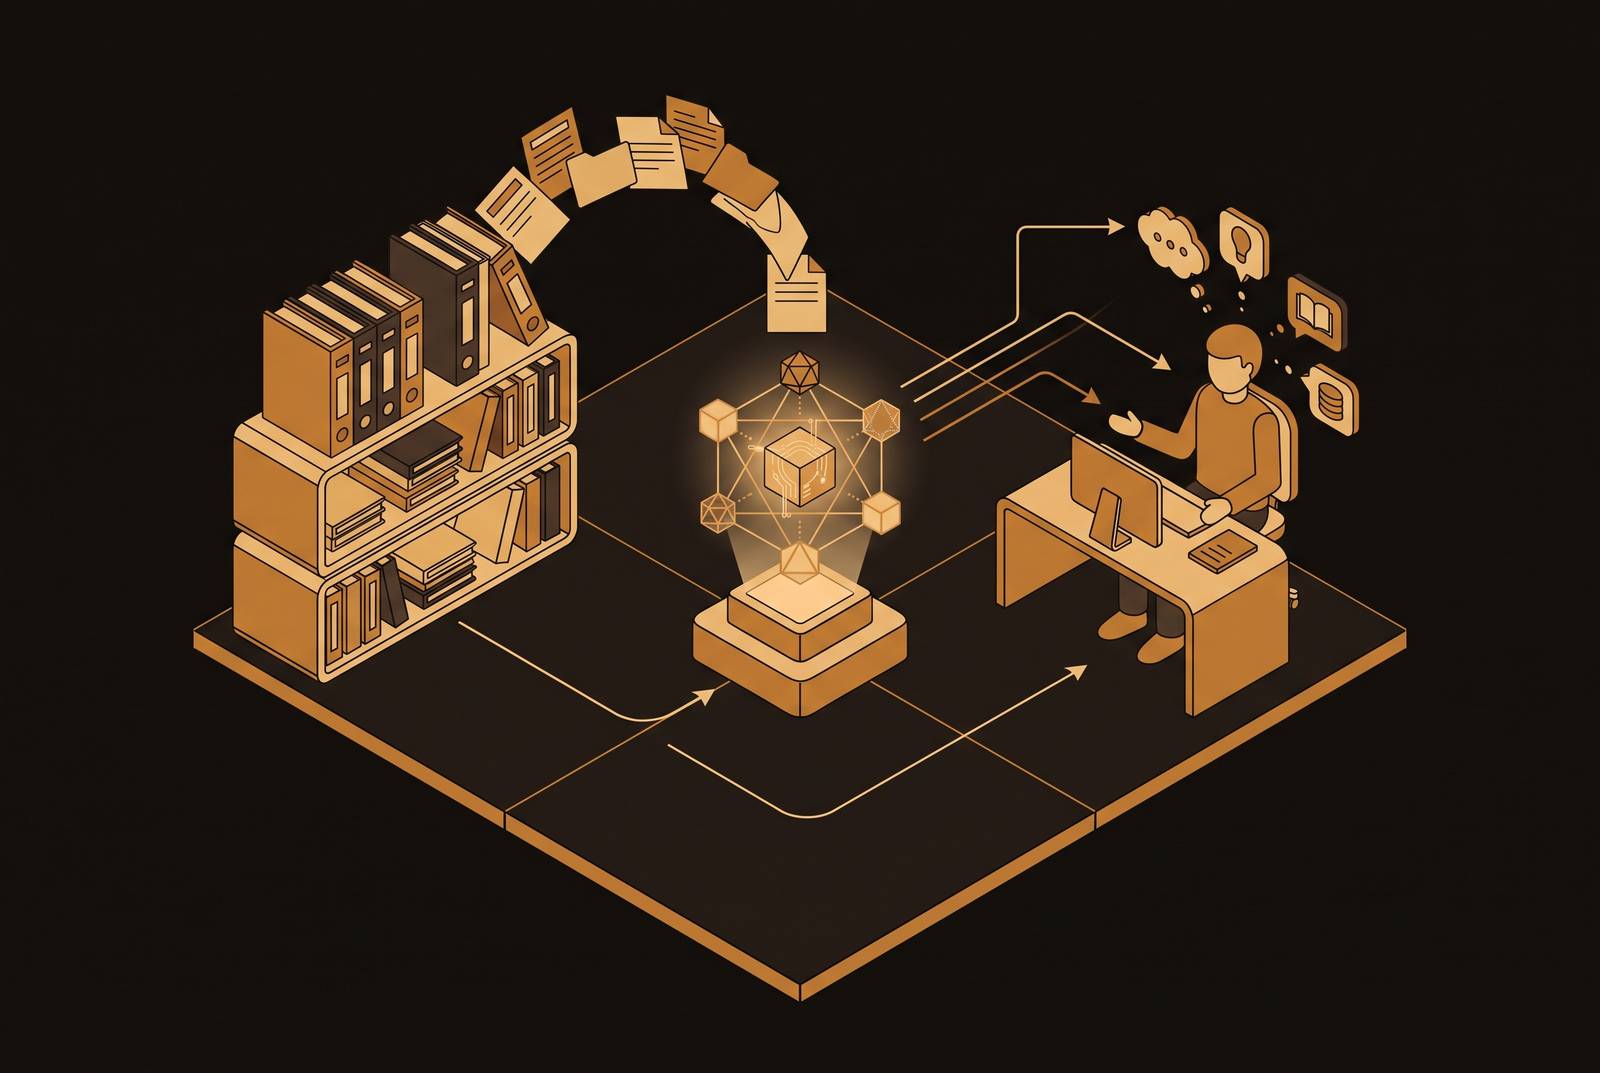
An AI agent trained on internal playbooks is valuable only when it can complete an onboarding workflow. Completing that workflow requires an architecture that retrieves approved knowledge, triggers provisioning steps, and hands off to the right human from a single interaction. The playbook layer makes that architecture production-ready by connecting what the organization knows to what the agent is allowed to do.
Why the first-day information problem is not a search problem
A new hire can have access to the company wiki and still lack a usable answer about configuring VPN. The instructions may exist, but the employee cannot tell which version is current or whether it applies to their role. A policy document may explain how much vacation people get while saying nothing about whether they work late on Fridays. These are different gaps, including failed retrieval, missing context, and uncaptured norms. Putting more documents in a portal does not close them.
The friction grows because onboarding is a dependency chain. The employee needs the right account, policy, training, and person to ask before they can get to work. When a link depends on a manual exchange, delays and repeated questions compound. For onboarding to work, the system has to link what the employee learns to what they need to do next and spot when the information is missing.
What separates a playbook-trained agent from a chatbot that happens to know your policies
A plausible answer is not necessarily an answer the organization can stand behind. A chatbot may describe steps that sound right but do not follow the approved policy, current instructions, or the document version that applies. Retrieval-Augmented Generation (RAG) addresses that distinction by retrieving relevant passages from indexed internal documents before generating a response grounded in organizational material. That grounding gives the organization a way to account for its answers, though a source that cannot be trusted still has no authority.
The practical test is whether the agent can identify the document and version behind an answer. Without that provenance, fluent language conceals whether the response reflects an approved source. Internal playbooks supply the distinctions that generic training cannot, including firm-specific billing conventions, jurisdiction-specific procedures, and role-specific onboarding paths. An answer must reflect these details to be correct for this employee in this organization. They are not optional refinements to an otherwise complete generic response.
An architectural evaluation therefore rests on five criteria, namely grounding in approved material, traceability to its version, role-appropriate scope, connection to workflow actions, and contextual human handoff. These criteria apply equally to purchased systems and agents built internally. Indexing Slack threads and past project files can also recover part of the tacit layer that formal policies omit. However, surfacing how people actually work is not the same as establishing what the organization approves. The playbook layer must keep track of that difference so that passages about how people work carry only the authority they have.
How the playbook layer is built before any agent goes live
Before indexing begins, the source material needs an audit for recency and authority. Duplicate documents, outdated copies, and contradictory policy files give the agent conflicting material from which to respond, making knowledge-base quality the binding constraint on performance. The operational work is to establish a single source of truth for each policy domain and identify which material belongs in it. A capable retrieval system cannot compensate for an unresolved disagreement between its sources.
That work also needs an owner after deployment. Each policy domain needs someone in charge of updates so that the knowledge base changes when the policy changes. Otherwise, a correct answer at launch can become an outdated answer later without any change to the agent itself. Source preparation is therefore an ongoing responsibility. The indexing of conversational history also needs to be reviewed as the way people work changes.
The collections themselves must reflect how the organization works. Separate collections for Engineering, Sales, Legal, and Operations allow the agent to retrieve from the employee’s function first, using role information from the HRIS. Universal company content provides the fallback for cross-cutting questions. This makes role a boundary on retrieval, keeping a sales hire from getting an engineer’s access checklist just because its wording matches the request.
Permissions form a separate boundary and must be enforced at retrieval time. A document’s relevance to a question does not grant the employee access to it. Restricted HR or personnel material must remain outside the retrieval scope of employees who lack permission to see it. Role-scoped collections select the material that applies, while access controls keep out material the employee has no permission to see. Both belong in the playbook layer before the agent handles real onboarding interactions.
The three actions that turn retrieval into an onboarding workflow
Once the knowledge layer is reliable, the next test is whether an answer advances the task. A request about email setup or VPN configuration may call for instructions, a provisioning request, or an approving manager. The first action is a provisioning trigger that follows the route encoded in the playbook. The agent’s job is not simply to retrieve the setup document but to determine which of those paths applies. That decision closes the gap between knowing what should happen and starting it.
Repository access makes the distinction concrete. Returning access instructions leaves the employee responsible for interpreting the process and finding the next owner. A workflow-capable agent uses the playbook that applies to decide whether to give those instructions, send a request to IT, or notify the approving manager. The correct outcome depends on the approved route. The agent can finish the exchange by starting an approved process, even if it does not grant access itself.
The second action is ticket creation and tracking. When support is required, the agent creates the ticket, assigns it to the right owner, and gives the new hire a status record. A VPN request then has a visible place in the onboarding process. Across these dependencies, the agent shows what is ready and what remains pending.
The third action is human handoff with context. The agent may be able to answer a benefits enrollment question from approved material, while a compensation question or compliance edge case may go beyond what it is allowed to handle. In that case, the workflow routes the interaction to HR, IT, or the hiring manager with the conversation context attached. The employee does not have to reconstruct the exchange for the next person. Human judgment is therefore part of the workflow’s completion path.
Why role-based personalization is an architectural requirement, not a UX nicety
These action paths cannot be reliable if every employee enters the same undifferentiated workflow. A sales hire needs CRM access, commission policy, and outreach SOPs. An engineer needs repository permissions, security onboarding, and infrastructure docs. A manager needs team setup, approvals workflows, and leadership resources.
The HRIS provides the routing signal by supplying the employee’s role at the start of the session. That signal scopes the knowledge collection and informs which provisioning and escalation path applies. Without the integration, the agent defaults to generic content even when a more specific playbook exists. It can then retrieve a valid procedure and still produce the wrong outcome because the procedure belongs to another role. Personalization is structural precisely because correctness depends on this context before the answer is generated.
In legal onboarding, a new associate needs matter-management SOPs for their jurisdiction and the billing conventions they must follow. In healthcare, a new clinician needs documentation workflows, HIPAA compliance requirements, and credentialing steps. In automotive and manufacturing, technicians, engineers, and service advisors need distinct document sets covering model-year-specific repair procedures, safety protocols, and compliance documentation. These differences also govern escalation, which must follow the employee’s role. When the path has rules it must meet, sending a request the wrong way can cause a compliance issue as well as lost productivity.
Governance and readiness requirements before an onboarding agent handles real HR data
For the agent to be ready for production, the controls must be in place before it handles real HR data. Without those controls, the agent is still run as a pilot, even if it has real users. The NIST AI Risk Management Framework provides an organizing structure through its four functions, namely Govern, Map, Measure, and Manage. The organization must be able to govern the agent’s task performance.
In practical terms, production requires tested guardrails, answer-quality and policy-drift monitoring, retrieval-time access controls, rollback procedures, and defined success metrics. Guardrails establish boundaries, while monitoring makes deterioration visible after launch. Rollback procedures provide a response when the agent produces a harmful answer. Success metrics make it possible to distinguish a working deployment from one whose performance is degrading.
Readiness also has to be assessed at the task level. Tsinghua University’s April 2026 paper presents the LARA (LLM Agent Readiness Assessment) matrix as a framework for scoring readiness for agent substitution. Its T-IPO model represents each task as a structured eight-element tuple. This approach supports decisions about which onboarding steps to automate and which to keep human-in-the-loop. Readiness for a retrievable policy question does not by itself establish readiness for a judgment-heavy compensation question.
HIPAA and GDPR make knowledge-base governance non-negotiable in healthcare, while legal onboarding requires respect for matter confidentiality and jurisdiction-specific privilege rules. Across verticals, audit trails for policy acknowledgment are a compliance requirement. For organizations with strict data residency requirements, on-premise deployment is an option that keeps HR data within their own infrastructure. These governance decisions establish the conditions under which measured performance can justify continued operation.
Measuring what the onboarding agent actually changed
Measurement begins with the first cohort the agent handles. The core operational measures are time-to-first-answer, reduction in repeated support tickets, provisioning delay reduction, day-one readiness rate, and manager hours recovered in the early onboarding period. An answer that arrives faster does not on its own show that access arrived sooner or that the employee was ready on day one. The measures need to follow the dependency chain that the agent is meant to improve.
Futurum Group’s 1H 2026 Enterprise Software Decision Maker Survey finds that the main way to judge AI is shifting from productivity metrics toward its direct effect on finances, including revenue growth and profitability. For onboarding, that puts more weight on the work people can now take on than on time saved alone. Manager hours spent answering retrievable onboarding questions are a concrete cost that can be tracked. Getting those hours back frees people to do work that needs human judgment. It does not, by itself, establish a financial return.
Citation rate measures the share of answers traceable to a specific document, while escalation rate measures the share routed to a human because the agent cannot answer. Policy-drift alerts show whether answers keep up when their source documents change or fall behind them. These measures must be read together because an appropriate handoff can be the correct result for a task kept human-in-the-loop. Faster responses are not an improvement if their grounding deteriorates.
KPMG’s mid-2026 AI Pulse reports that only a small minority of enterprise leaders have established ROI on AI deployments. Instrumenting an onboarding agent from day one gives the organization a basis for judging both value and reliability. An agent that demonstrates dependable completion of a defined workflow can earn expansion into cross-boarding, manager onboarding, and compliance refreshes. The playbook layer makes that expansion governable, while measurement makes it defensible. The agent earns a broader role by proving the work it completes.